

Overview
The Raily Agentic Layer controls how the intent analyzer navigates and retrieves content from your data sources. Raily’s search isn’t a plain keyword match - it’s an agentic search. Before each query runs, the intent analyzer reads it, figures out what’s actually being asked, and adapts the search to fit. For end users, that means fewer irrelevant results and answers that match the question they actually asked. Every feature is configurable per endpoint. You edit these settings in the Raily app, on the endpoint’s Search config page and on each Source’s Data description page. See Where you change these settings.Search Behavior
Controls how Raily searches your indexed content when an AI agent issues a query.Intent understanding
The intent analyzer classifies what you’re trying to do: looking up a known piece, asking a factual question, exploring a topic, comparing things, or following a step-by-step guide. The search adapts to that intent.Freshness awareness
Recognizes time-sensitive queries (“latest”, “this week”, “yesterday’s update”) and prioritizes recent material. For fast-moving topics, it tightens the time window even when unspecified.Multi-angle retrieval
For comparisons or multi-faceted questions (“compare A and B”), the intent analyzer runs several searches in parallel, one per angle, and merges the results, giving balanced evidence from each side.Vocabulary bridging
The intent analyzer knows the vocabulary of your content and quietly rewrites queries into the terms the source actually uses, so casual phrasing still finds the right passages.Filters
Filters narrow the retrieval scope before search runs. Raily handles them two ways: automatically inferred from the query, or explicitly configured per request.Inferred from natural language
Phrases like “articles from last week” or “only in the opinion section” are recognized and turned into precise filters automatically. The search is schema-aware, applying the right filter for the right value, including:- Dates and time ranges - “this week”, “in 2024”, “before the election”
- Authors and contributors - by name, with fuzzy matching
- Sections, categories, or topics - opinion, sports, business
- Content type - articles, reviews, interviews, recipes
- Tags, entities, and other metadata your content provides
- Several values that must all match - “the piece Dana Levi and Amir Cohen wrote together” finds pieces that list both people, not pieces by either one
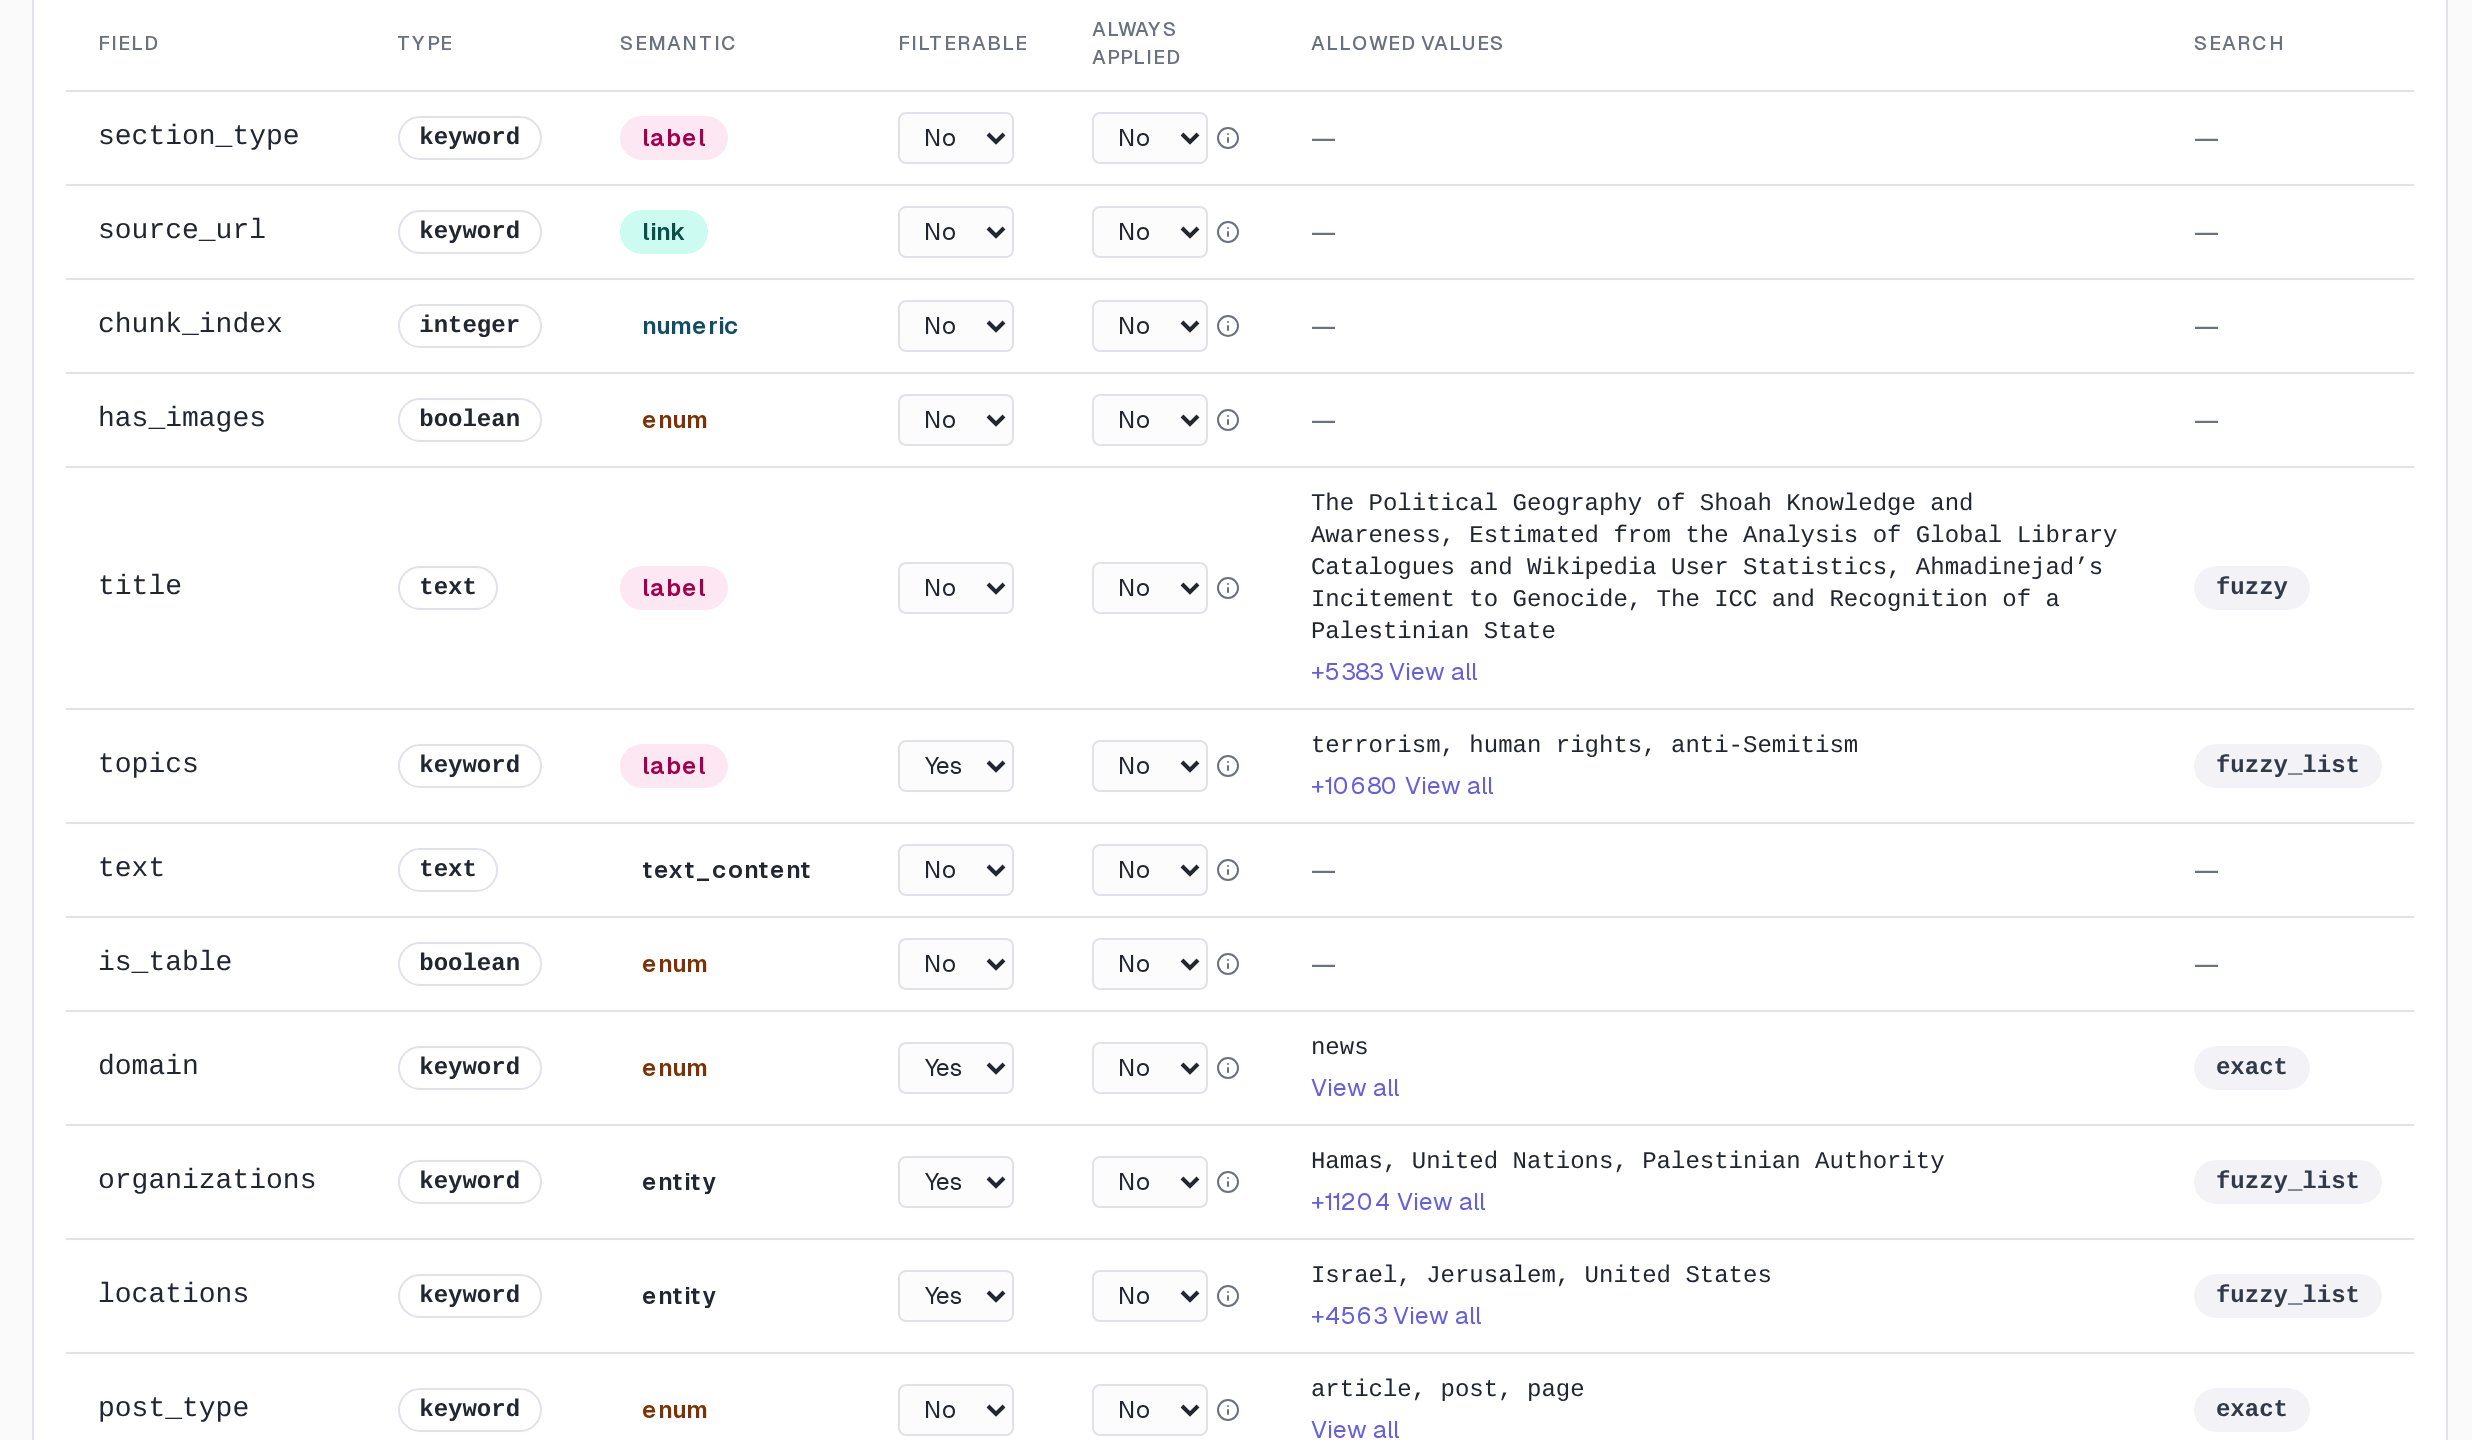
Filterable and Always Applied on a Source's Data description page
Explicit configuration
Filters can be set explicitly by the calling application on any metadata field, useful when the UI already knows the scope (a section page, a saved view, or a permission boundary).Retrieval Granularity
What it is
Each document can be split into smaller, focused passages (chunks), and the search returns the chunks that best match your query.Why we do it
- More precise answers. Returning the exact passage that answers your question beats returning the whole piece.
- Better ranking. Short, focused passages let the search score relevance more accurately.
- Faster reading. You see the relevant part first, with a link back to the full document.
What a chunk looks like
A chunk is a short, self-contained section of a document (typically a few paragraphs) and carries the source’s metadata (title, author, date, link). Multiple chunks from the same document can appear when more than one passage is relevant.Chunks or full document?
The intent analyzer decides automatically:- Chunks - focused passages, used for factual lookups, topic exploration, and comparisons.
- Full document - the complete piece, used when order or context matters (known articles, in-depth analysis, recipes and guides).
When nothing closely matches
Some queries have no strong match in your content. Raily uses two bars to decide what to return:- a retrieval bar, the minimum match quality for a passage to be considered at all, and
- a confidence bar, the higher quality a passage needs to count as a strong match.
present_both(default): show them as suggestions. Strong matches come first. Weaker ones follow under a header you set, such as “We didn’t find an exact match, but you might find these useful.” The reader gets something related instead of an empty page.drop: hide them. Return only strong matches. If nothing clears the confidence bar, the search returns no results. Use this when a plausible-but-wrong answer is worse than none.off: show everything together. Return every result above the retrieval bar in score order, with no suggestion header and no split between strong and weak.
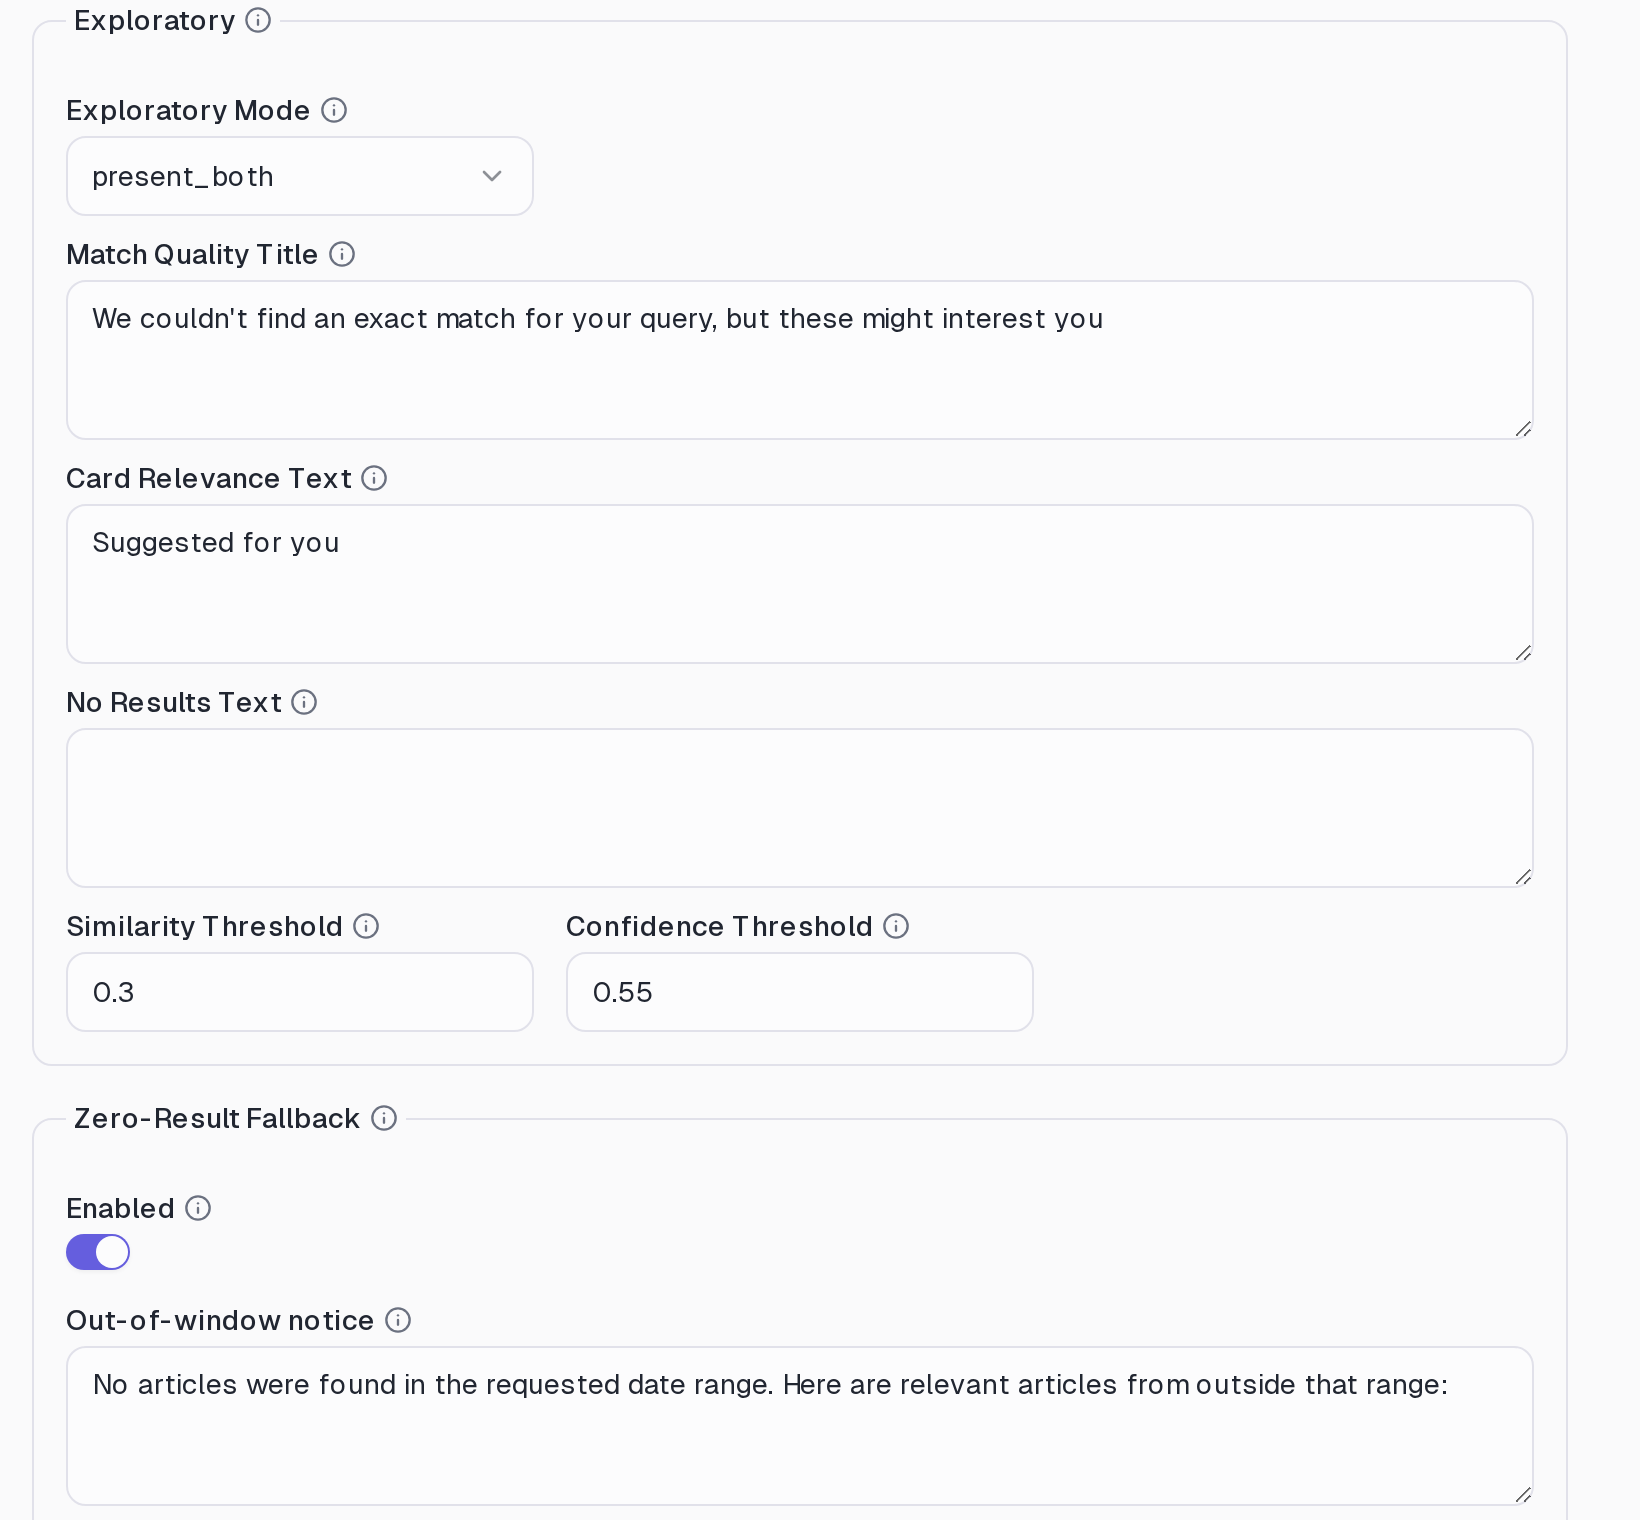
Exploratory section of Search Behavior
Publications your archive doesn’t include
Readers sometimes ask for a publication your archive doesn’t hold, or ask for help with their subscription or login. Raily can recognize these requests and answer with a line you write instead of serving unrelated results. Raily sets up the list of publications your archive doesn’t include; you write the replies in the Replies About Publications And Accounts section of Search Behavior:- Excluded Source Ask Back: a reply when the reader asks only for a publication you don’t hold, offering to search your own content instead.
- Excluded Source Notice: a line shown above your results when the reader pairs that publication with a subject you do cover.
- Service Request Reply: a reply pointing readers to customer service when they ask about a subscription, billing, login, the app, or newsletters.
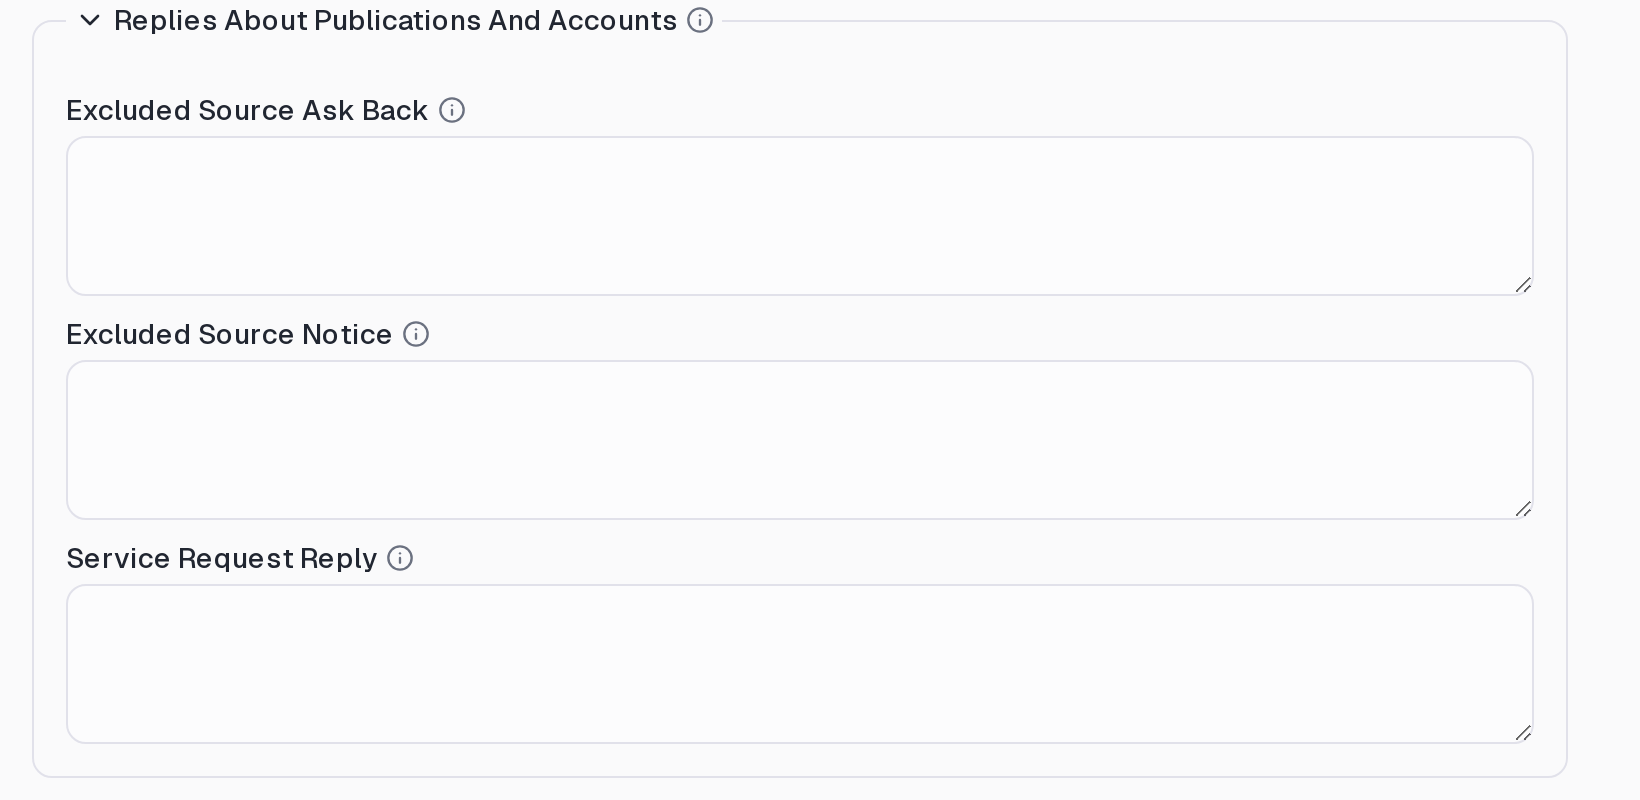
Replies About Publications And Accounts
Reranking
Search finds candidates by meaning. A reranker takes the top candidates and scores each one again, more carefully, against what the reader asked, then reorders them. The best answer moves to the top, and results that only look related can be dropped. The reranker scores results against a one-sentence restatement of the request that the intent analyzer writes. So when a reader follows up with “yes, find it for me”, the results are still judged against the article they asked about, not against those four words.Choose a reranker type
Open the endpoint’s Search config and go to Search Behavior. In the Reranker section, turn on Enabled, then pick a Reranker type: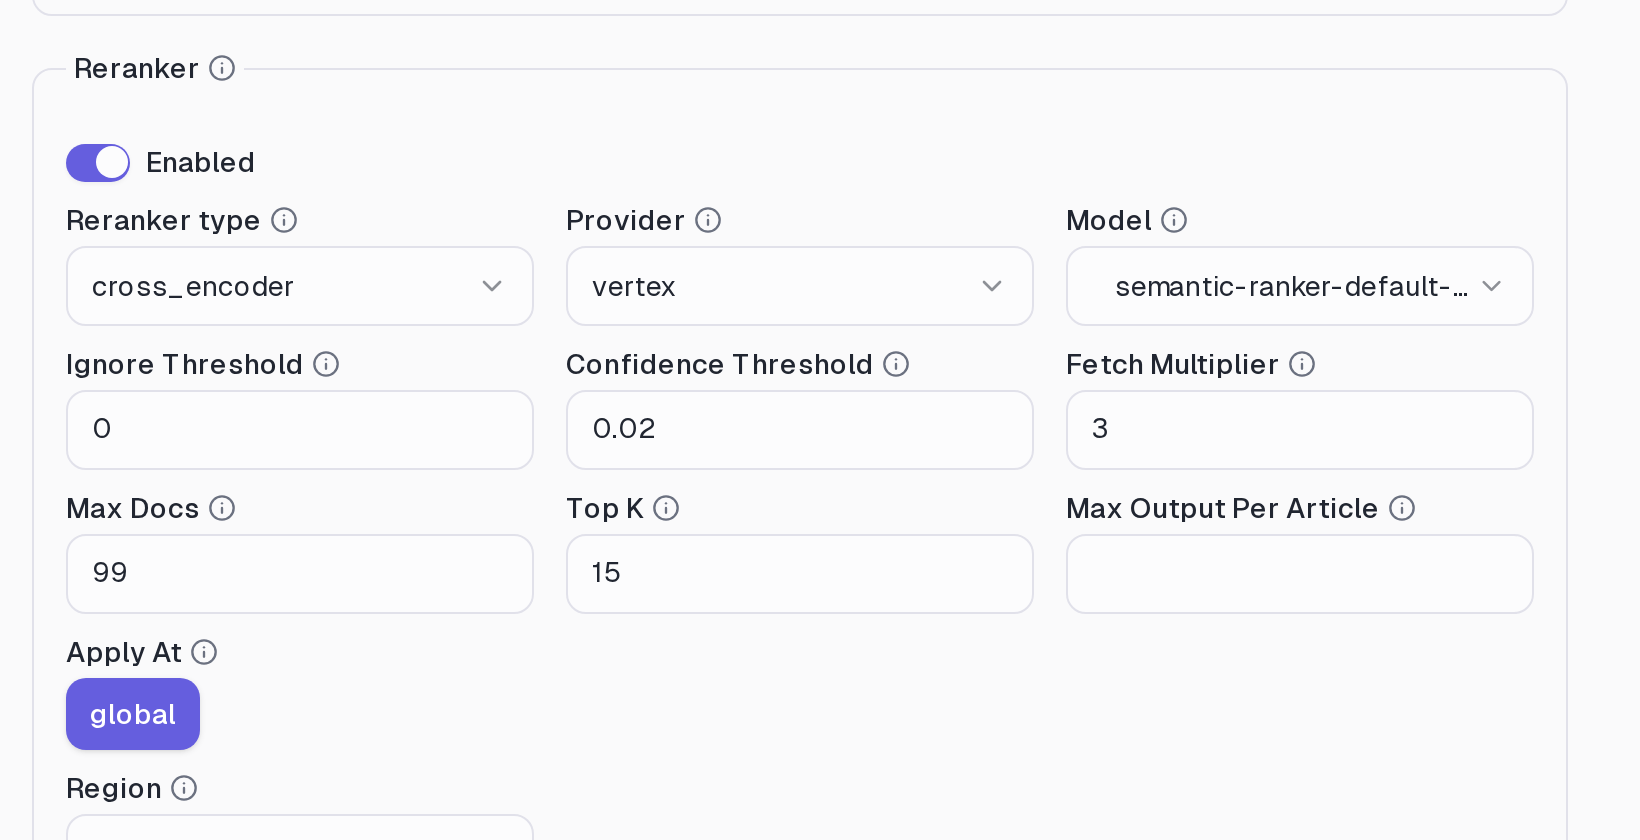
Reranker section of Search Behavior
cross_encoder: a dedicated ranking service. Fast, and a good default for most content.llm: a language model reads each result and grades how well it answers the request: off-topic, related, partly answers, or answers. Choose a Model from the list.
llm when results match the right words but miss the point of the question, for example when readers ask nuanced questions, compare positions, or ask for one specific piece among many similar ones. It costs more and adds some time to each search, because the model reads every result it grades.
Two thresholds decide what survives:
- Ignore Threshold: results scoring below it are removed. For
llmthe default removes off-topic results. - Confidence Threshold: results below it are shown as weaker suggestions (see When nothing closely matches). For
llmthe default counts a result as a strong match when it answers the request at least partly.
Rerank passages or whole articles
The reranker in Search Behavior works on the endpoint’s merged results. To rerank individual passages, or whole articles after chunking, set the Reranker on the Source’s Data description page instead. It needs an enabled Chunker first.Run LLM reranking on your own key
LLM reranking with a Gemini model can run on your Account’s own Google AI key. Assign Reranking to your key on the Model keys page. Cross-encoder reranking always runs on Raily.Result cards
When a result has no value for a field shown on its card, such as no author or no date, the card shows a default. You can change it per field on the endpoint’s Display tab: open a slot on the card and use When the field is empty to keep the default, choose Show nothing, or choose Show custom text (for example “Editorial team”). Apps that use an API key receive the same text in the result’s fields.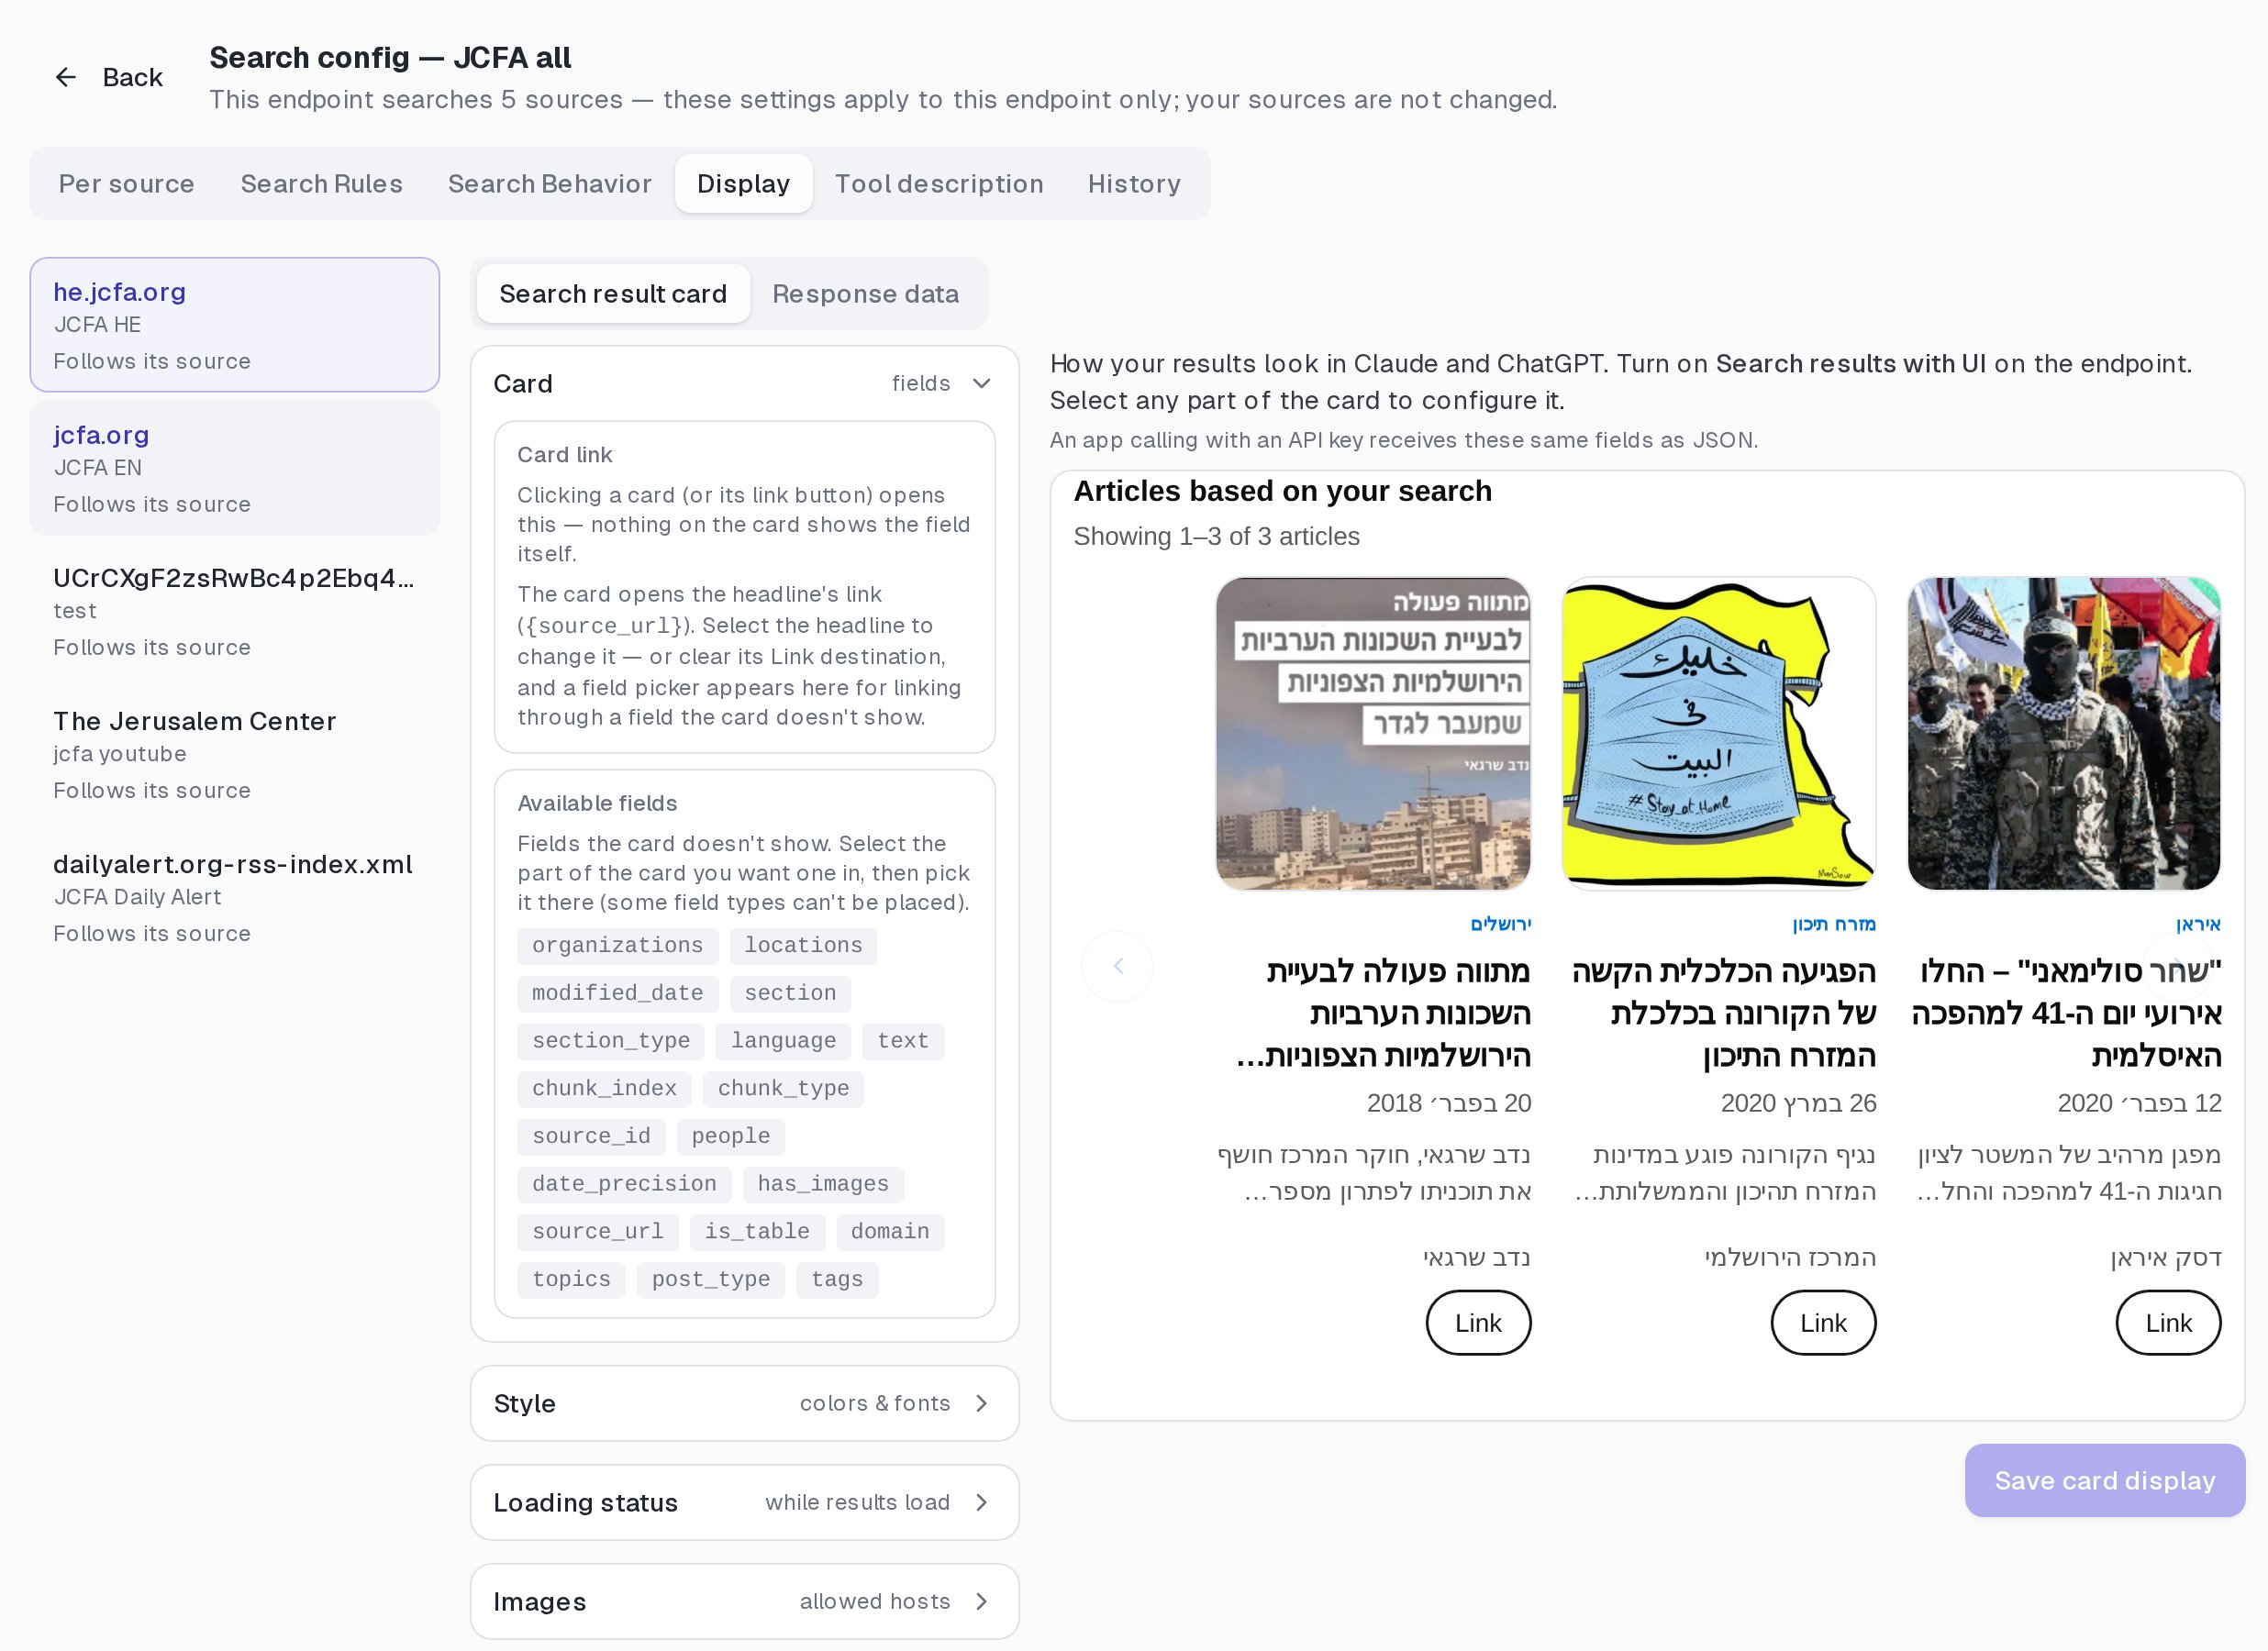
Display tab: select any part of the card preview to configure it
Rules
Rules tell the agentic layer how your business wants certain requests handled. You write each rule in plain language, and Raily applies it when it reads a request. Typical uses:- Keep a topic or content type in front for certain questions (“For analysis questions, prefer investigative pieces”).
- Map your readers’ wording to how your content is labeled.
- Set a default the reader doesn’t state (“When no date is given, prefer the last two years”).
1
Add a group
Click Add group and name it, for example
freshness. Groups keep related rules together.2
Write the rule
Click Add rule and type it in the box that says State the rule in plain language…. On an endpoint with several sources, use Applies to to limit the rule to some of them, or leave All sources.
3
Add an example
Each rule needs an example: a request a reader might send and the filter values you expect. The example shows Raily what the rule means in practice.
4
Save
Click Save rules. Agents use the new rules on their next search.
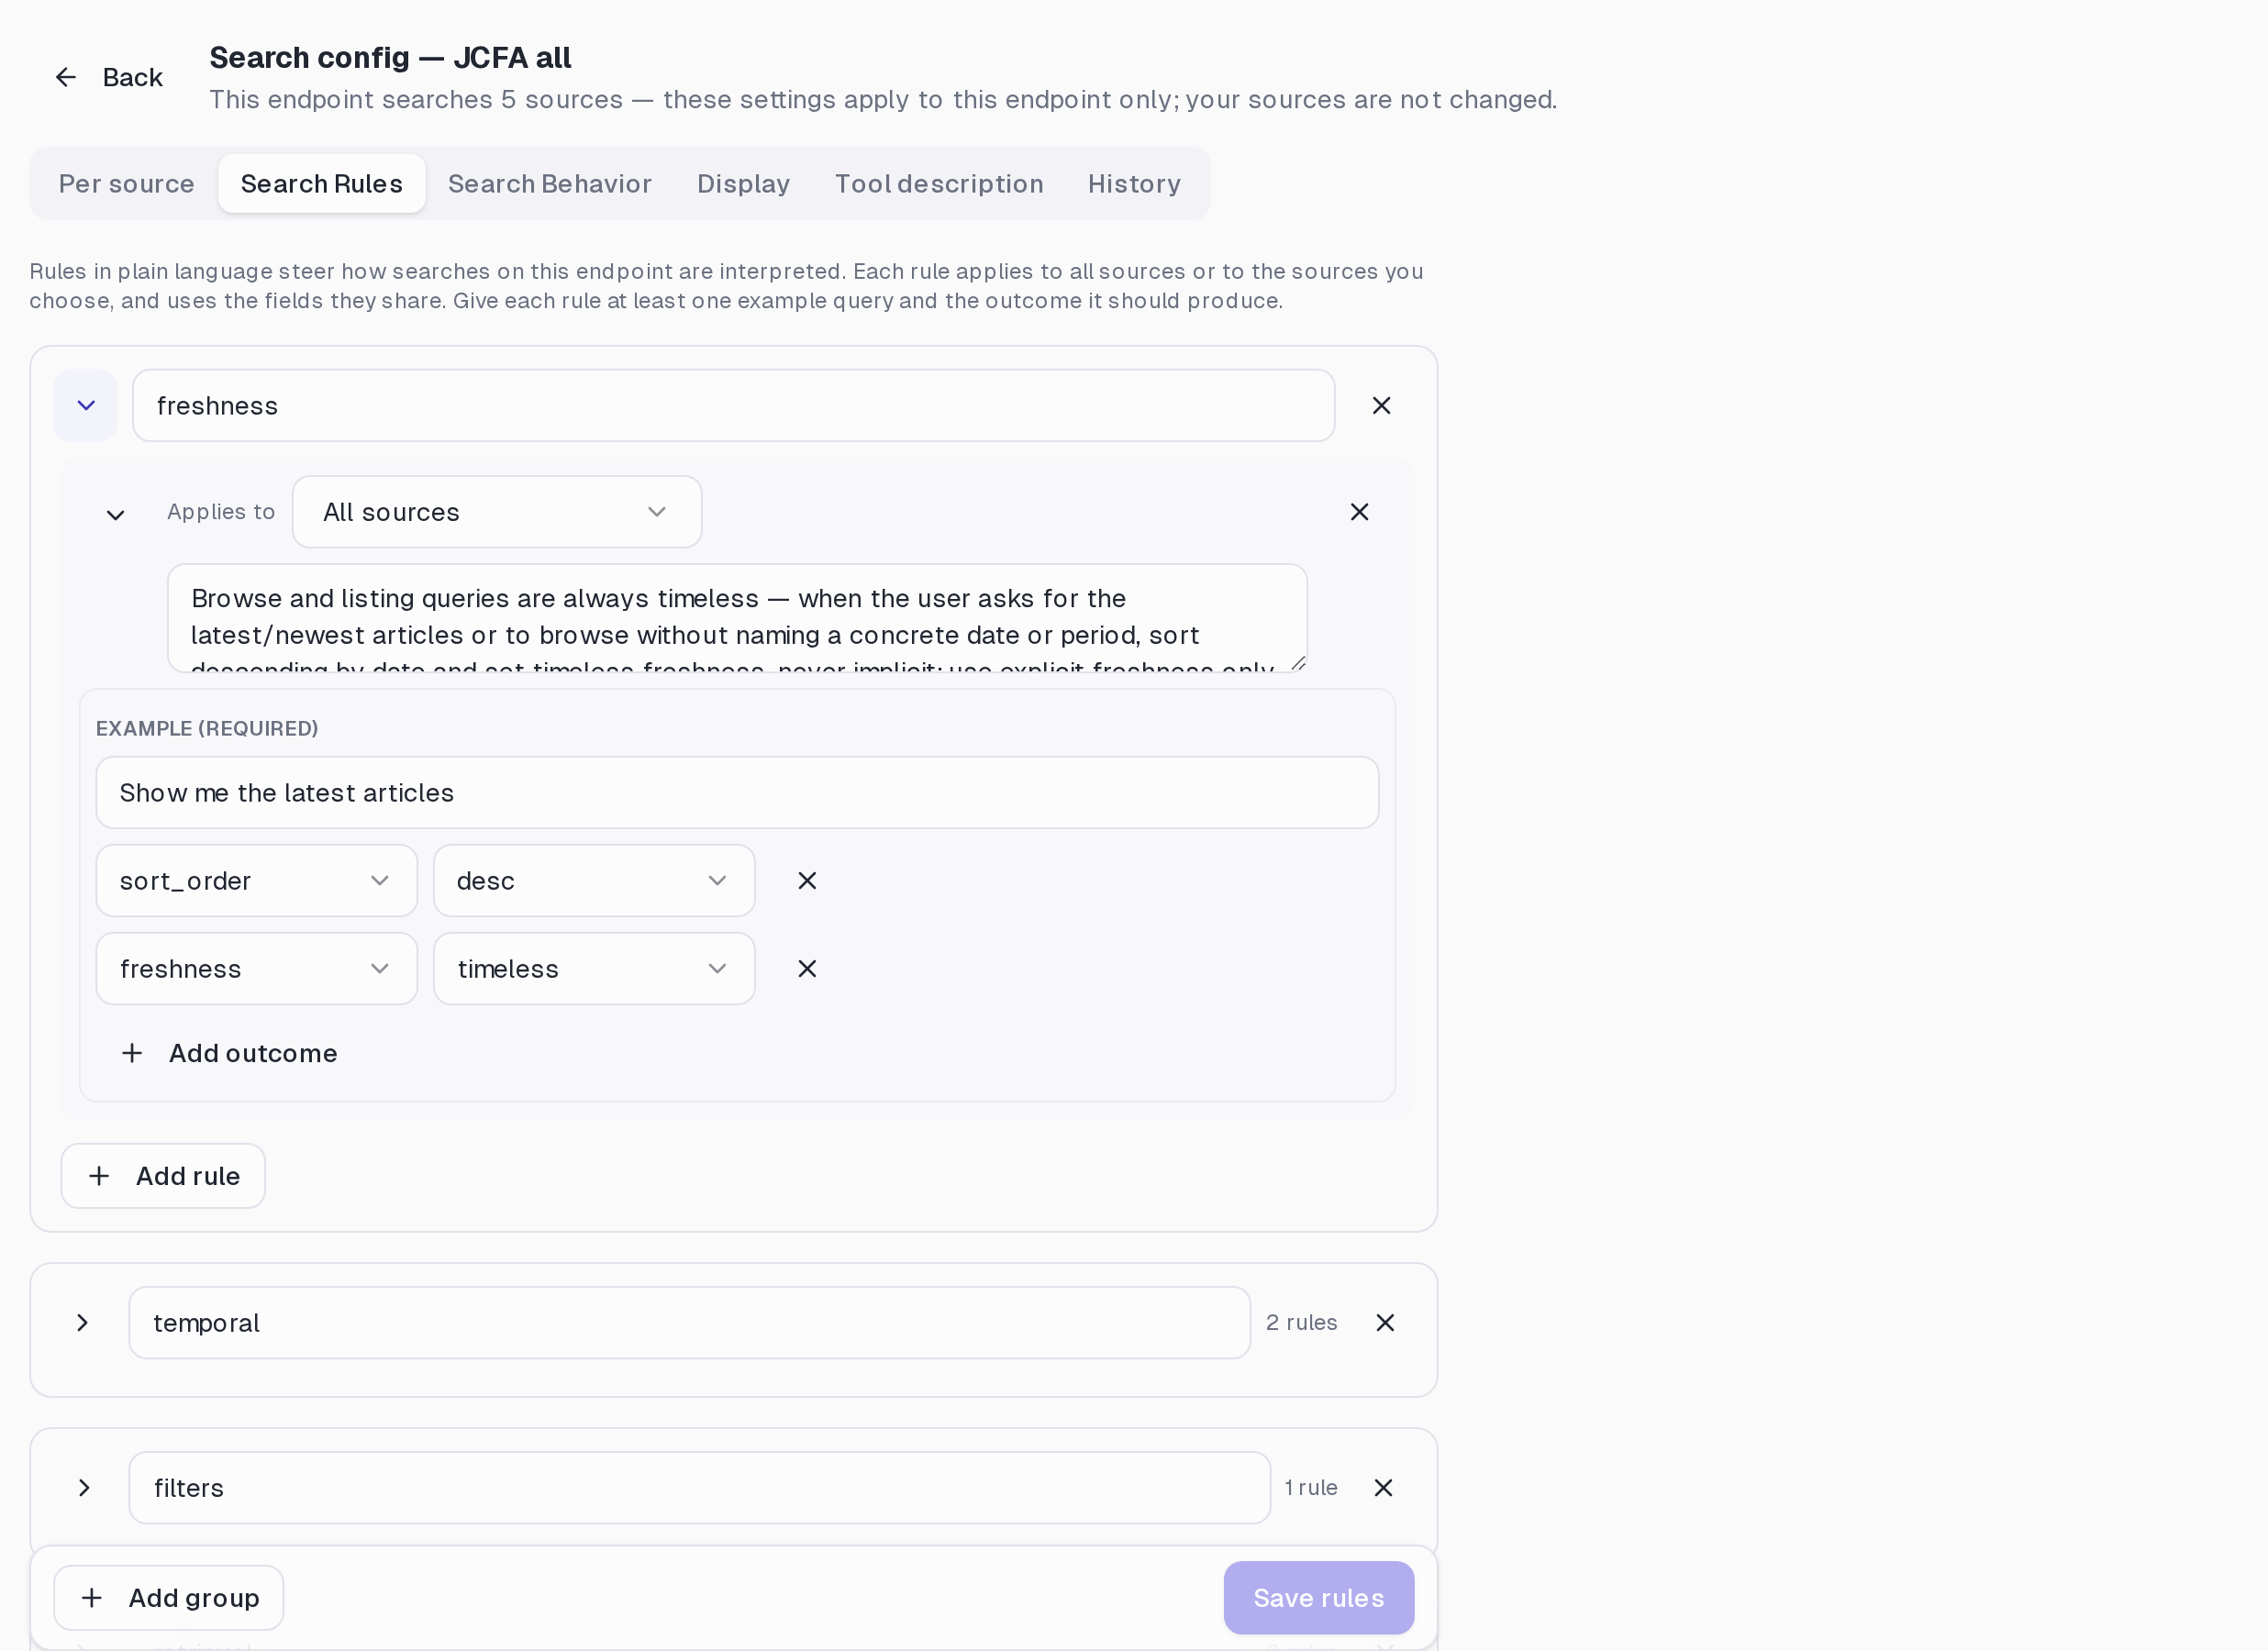
A rule with its example on the Search Rules tab
Where you change these settings
Search settings are edited in the Raily app. Raily writes a first version for you when you connect a Source, and every save is kept in History, so you can see what changed and restore an earlier version. On the endpoint, open the endpoint and select Search config. The page has these tabs: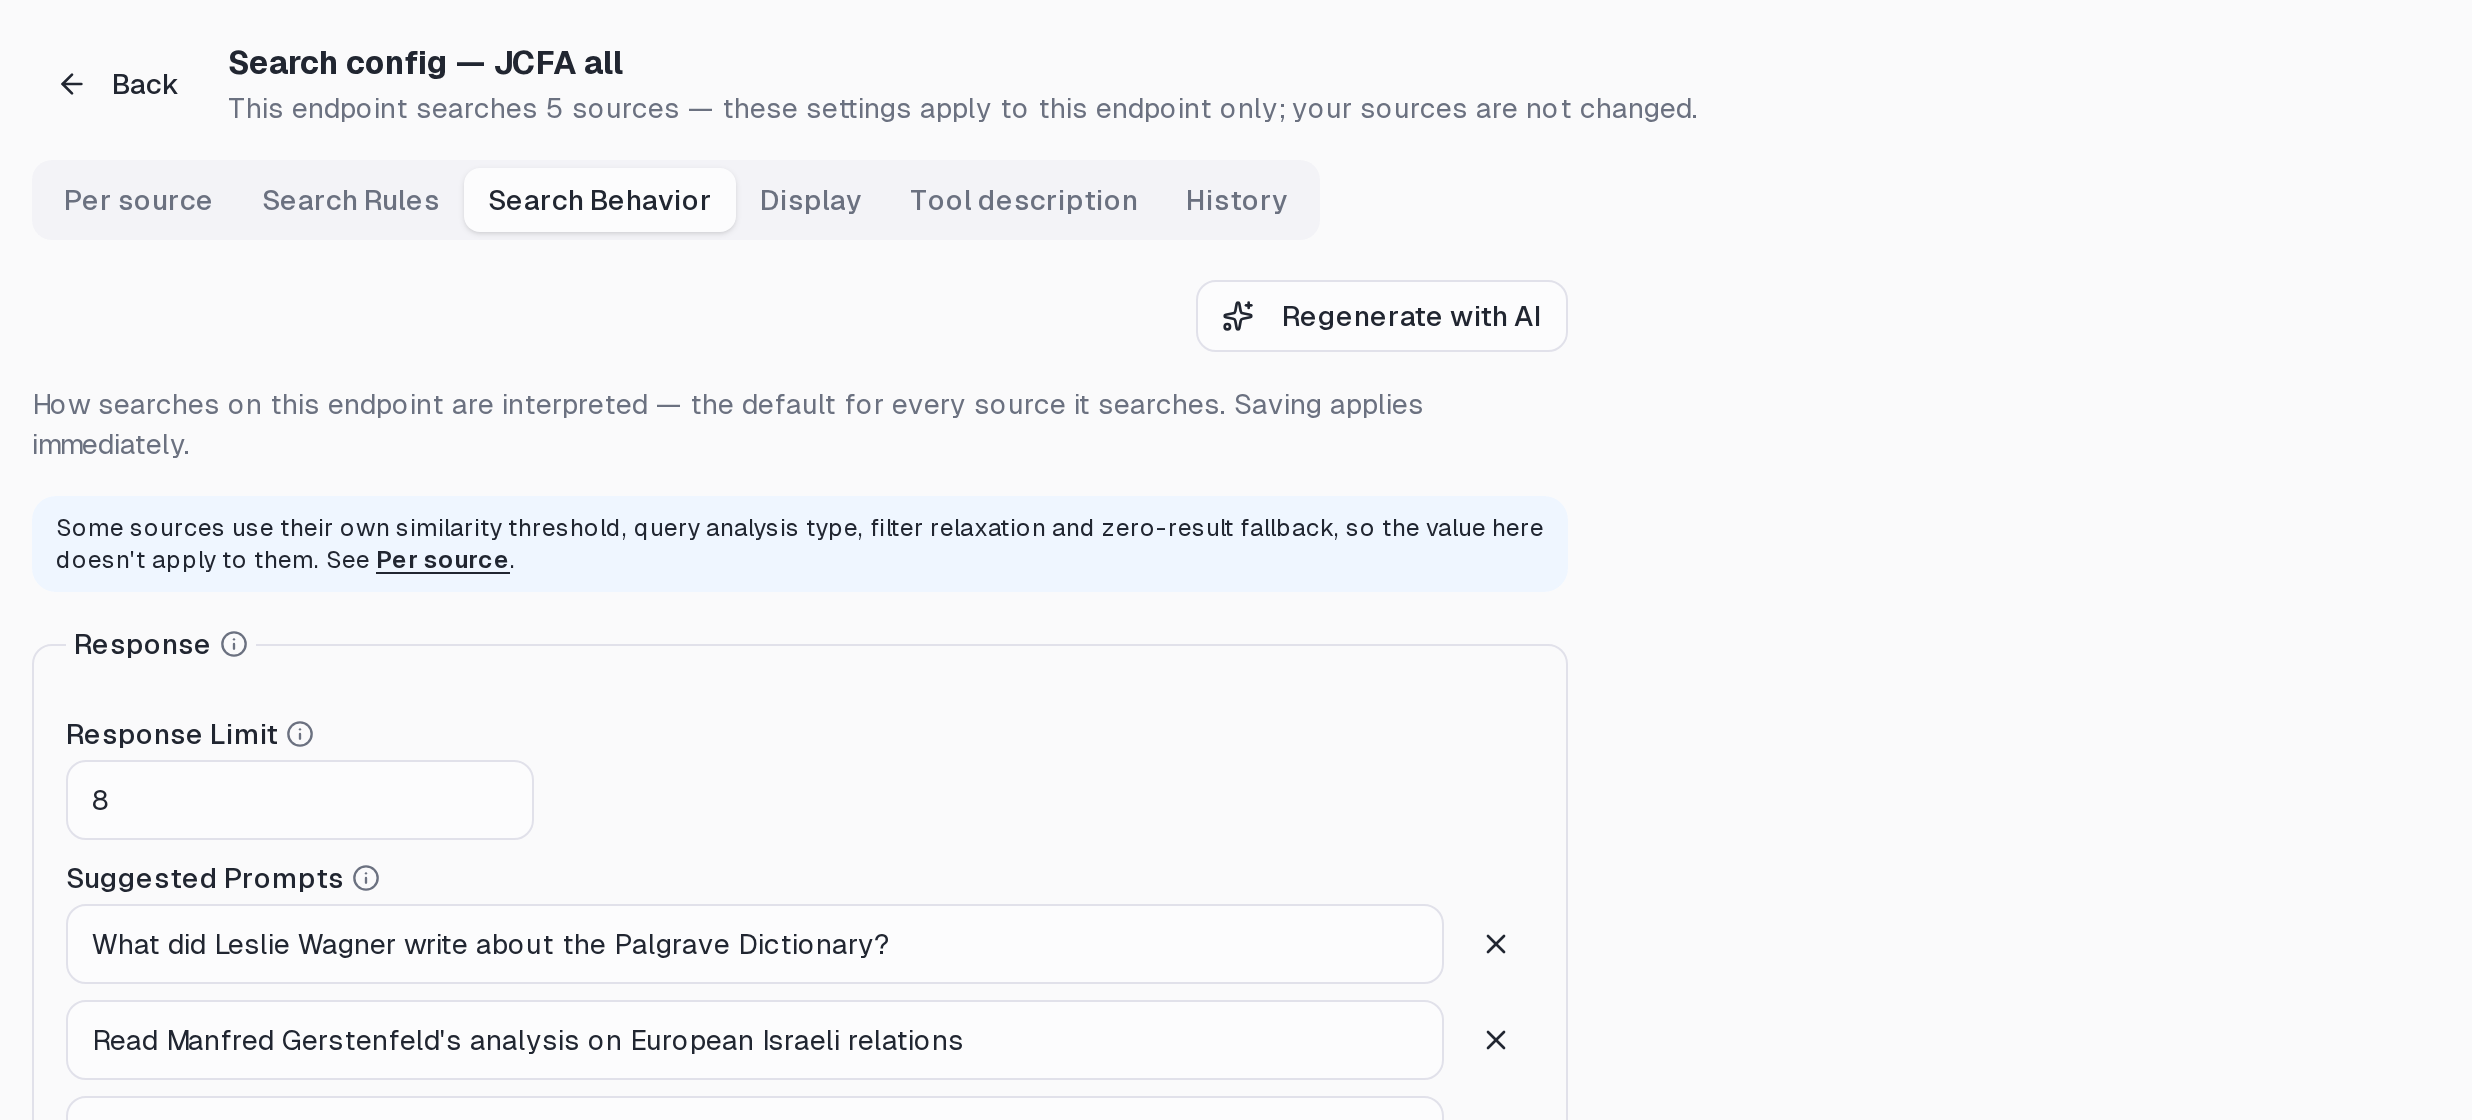
The endpoint's Search config page
- Per source - only on endpoints that search several Sources. Settings for each Source on this endpoint.
- Search Rules - rules written in plain language that shape how searches run.
- Search Behavior - result limits, the relevance and confidence bars, weaker-match handling, the zero-result fallback, query analysis, and the reranker.
- Display - how result cards look.
- Tool description - how agents see this endpoint’s search tool.
- History - every saved version.
Card display is shared by every endpoint that searches a source. If saving on Display would change cards on other endpoints too, Raily names them and asks you to confirm with Save for all.
Tune each source on a multi-source endpoint
The Per source tab lists the endpoint’s sources on the left (a dropdown on narrow screens). Under each name you see Follows its source, a count such as 2 set on this endpoint, or Not searched. Select a source to see its settings: search strategy, similarity threshold, query analysis type, filter relaxation, and zero-result fallback. A label next to each one tells you where the value comes from:- From source: the endpoint uses the source’s own value. Click Keep this value on the endpoint to pin it, so later changes to the source don’t reach this endpoint.
- Set on this endpoint: you changed it here. The label also shows the value it would fall back to. Click Reset to source to follow the source again (or Reset to endpoint default when the source has no value of its own).
- Endpoint default or Default: neither the source nor the endpoint sets it, so the Search Behavior value or Raily’s default applies.
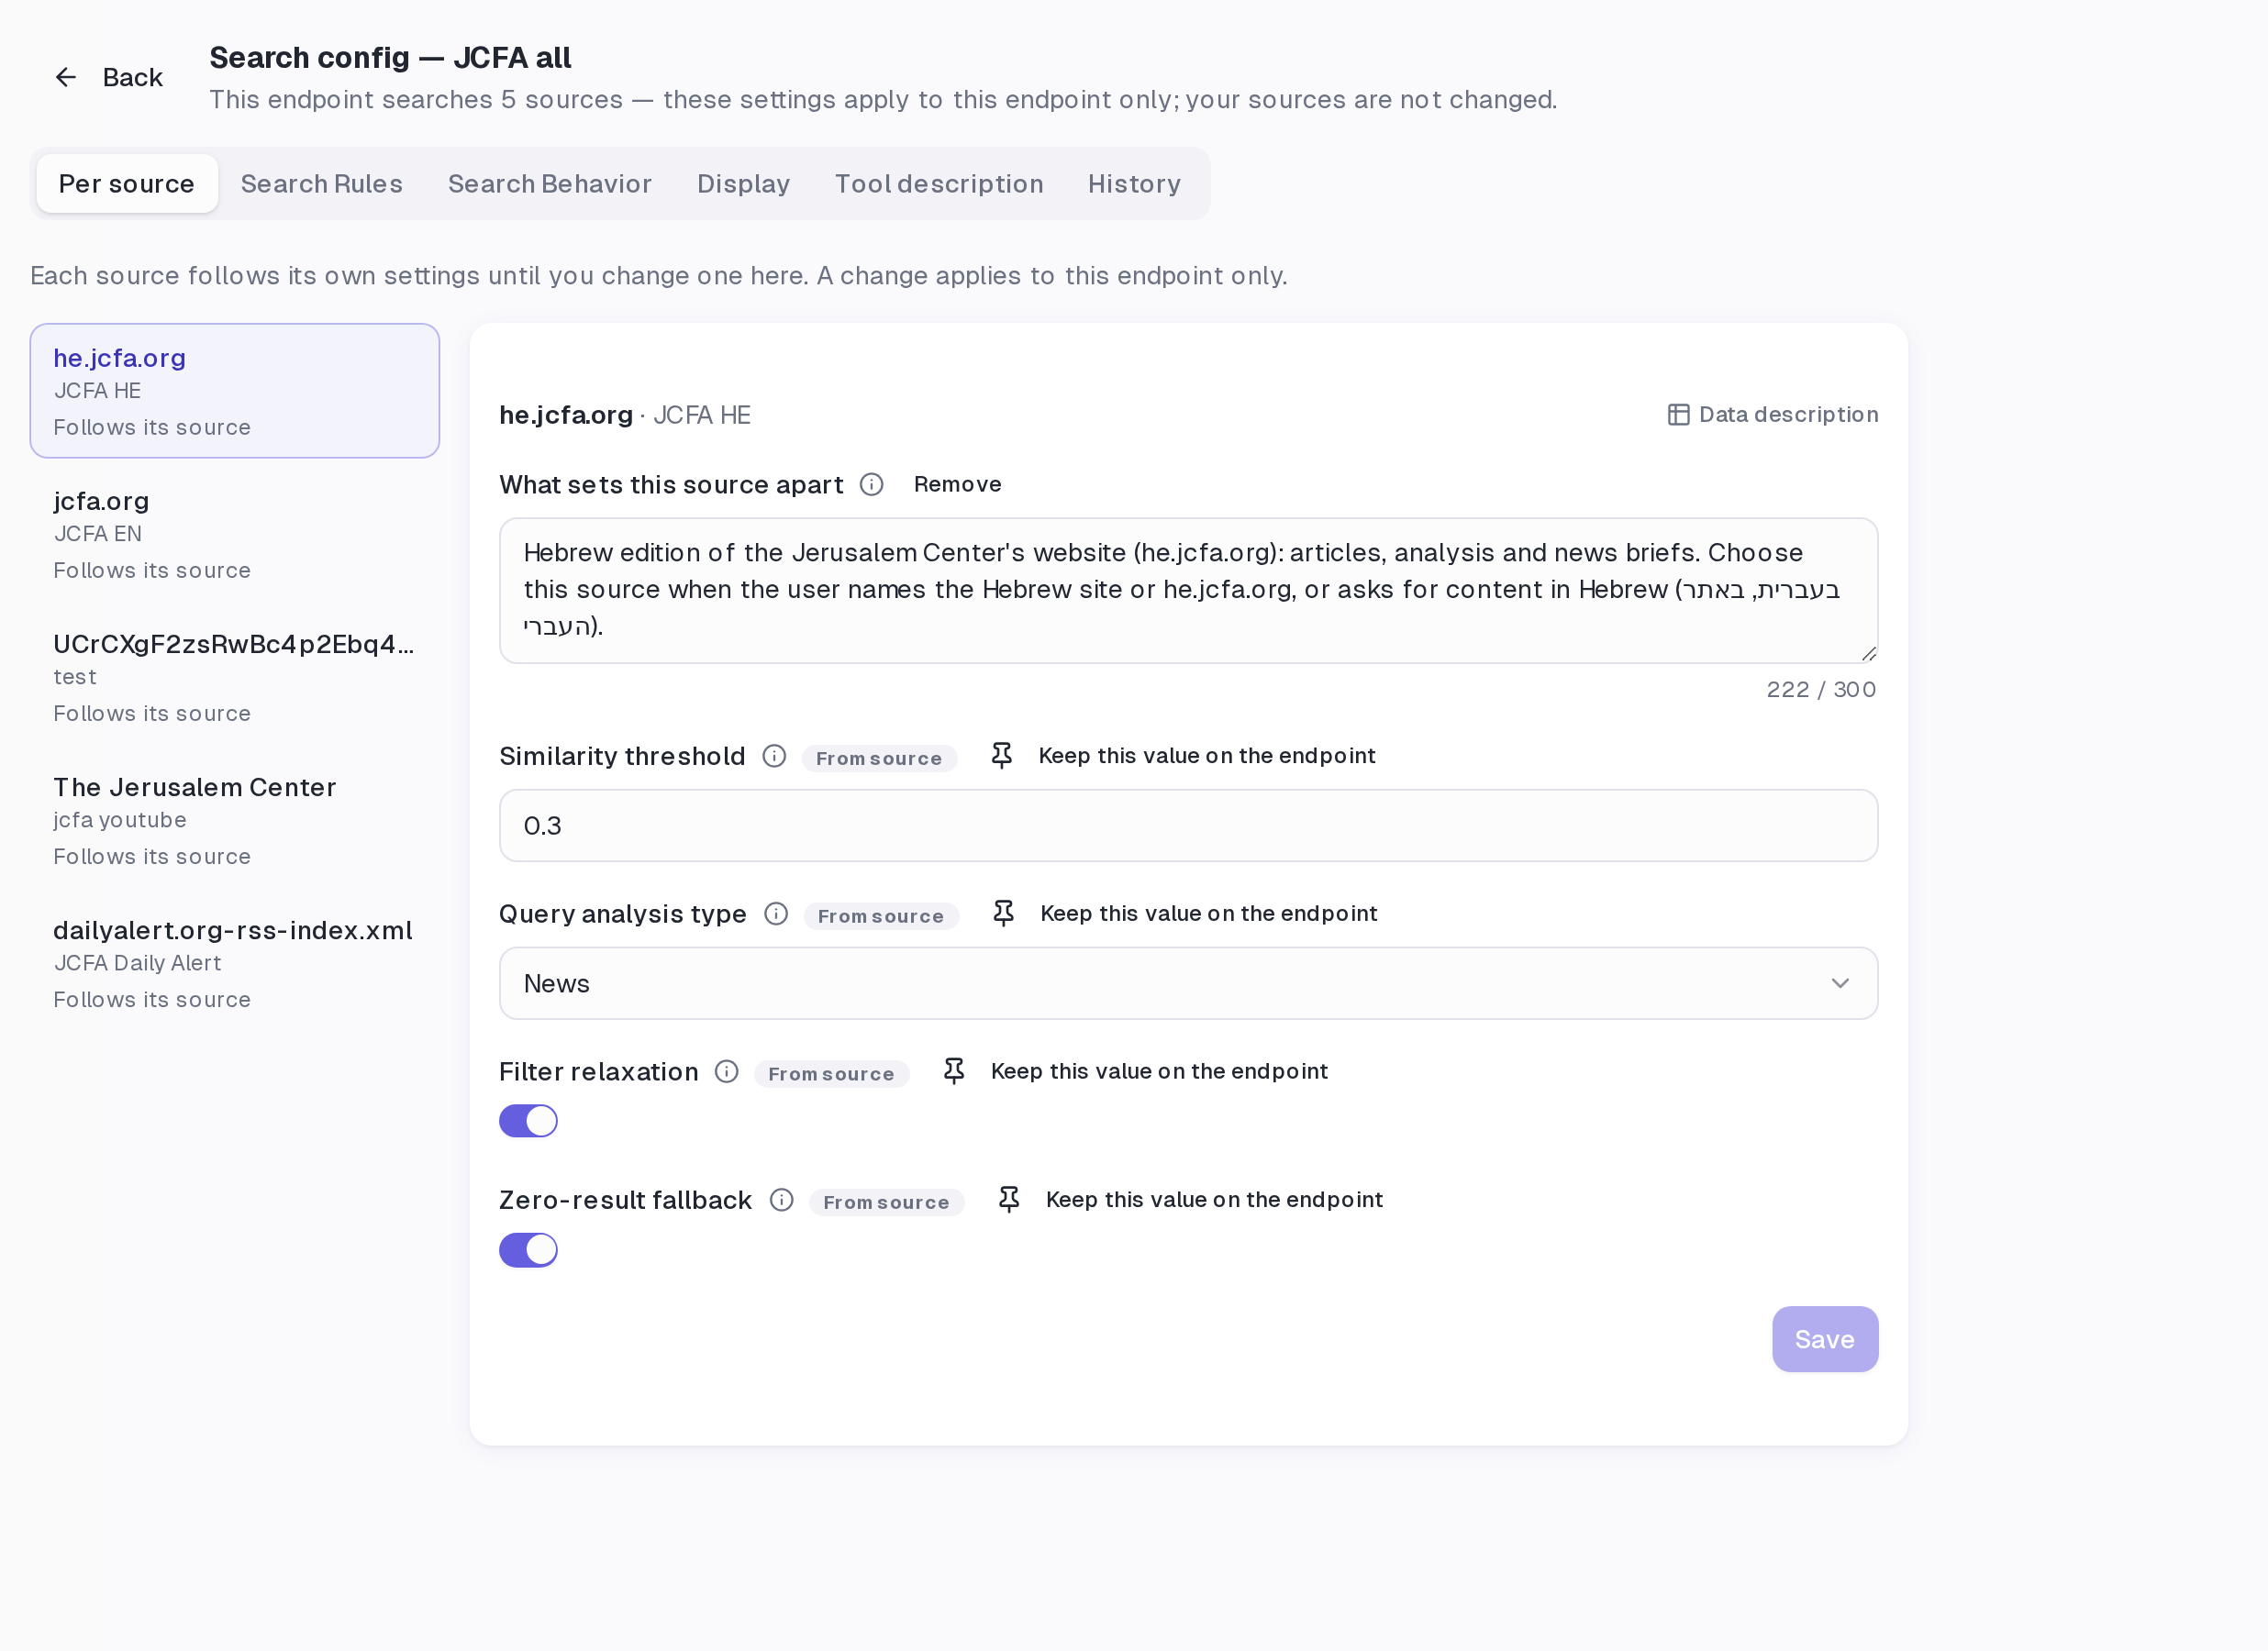
Per source tab on a multi-source endpoint
Next Steps
AI Endpoints
Expose your data to AI agents via authenticated endpoints